Hi, this is Wei Huang(黄炜)’s website!
I am currently a Ph.D in HKU, supervised by Prof.Xiaojuan Qi, Prof.Shiming Zhang. I am also co-supervised by Prof.Zhongrui Wang.
I obtained my bachelor’s degree in Jun 2023, supervised by Prof.Si Liu.

My research focuses on Efficient AI, Long-context AI, and Embodied AI.
✍️ Blogs
Selected NVIDIA Research blogs co-authored by Wei Huang.
Pushing Intelligence to 4-bit
NVFP4 across LLM training, inference, KV cache, attention, and real-time long-video generation.
NVIDIA Research BlogKV Cache Compression and Its Infra Problems
Why production KV compression must work with FlashAttention and paged memory, and how TriAttention closes the gap.
NVIDIA Research BlogScaling Video Training with Parallelism
Sequence-parallel systems for long-video understanding, generation, and RL, from MM-SP to Balanced SP.
NVIDIA Research BlogWhy Video Gen Is an Infra Problem
Why long-video generation increasingly depends on efficient training, memory, and deployment infrastructure.
💬 Invited Talks and Report
-
Long-WAMTalks
Oct 2026 Tsinghua University (Prof. Mengdi Xu's team) & Coco Matrix · NUS
Nov 2026 UC San Diego · NVIDIA Autonomous Driving 180+ attendees
Zhejiang University · HKU · ByteDance · Qingke Community · Human Five
Media -
Cosmos SimulationOct-Nov 2026Official
-
LayerRecallSep 2026Media
-
JoyAI-Video-EditJul-Aug 2026Media
-
TriAttentionTalksQingke Community · Talk by co-author Weian Mao (Aug 2026)MediaAI Era (May 2026)
-
Nemotron 3 Nano OmniApr 2026Official
-
QeRLTalks
Meituan · Huawei
Qingke Community · Watch talk (Nov 2025)
-
OmniVinciOct-Nov 2025Media
-
LongLiveTalks
NUS (Prof. Shuicheng Yan) · UC San Diego · HKU
ByteDance · Tencent
The Jiangmen (TechBeat) · Talk by co-author Shuai Yang (Nov 2025)
MediaAI Era · TechWalker (LongLive 1.0, Oct 2025)
TechWalker (LongLive 2.0, May 2026)
-
Long-RLTalksMeituan · Momenta · Huawei, among othersMediaSynced (Jul 2025)
-
VideoEspressoJun 2025TalksAI-Time · Watch talk
-
BiLLMMay-Jun 2024TalksAI-Time · Watch talk (May 2024)Media
IEEE Spectrum (May 2024) · Interview by Matthew Hutson
QbitAI (Jun 2024)
-
LLaMA3 QuantizationApr 2024
🔥 News
- 2026.08: 🎉🎉 One paper (Reinforcing Dual-Path Reasoning in Spatial Vision Language Models) is accepted by EMNLP’26!
- 2026.06: 🎉🎉 One paper (Anchor Forcing) is accepted by ECCV’26!
- 2026.05: 🎉🎉 Two papers are accepted by ICML’26! One for efficent long context compression (Tri-Attention) and one for diffusion quantization (Absorbing Quantization Error).
- 2026.02: 🎉🎉 One paper for 4D Vision-language Models (Learning to Reason in 4D: Dynamic Spatial Understanding for Vision Language Models) is accepted by CVPR’26! All the codes are opensourced now!
- 2026.02: 🎉🎉 One paper for extreme MoE-LLMs/VLMs compression (MC#: Mixture Compressor for Mixture-of-Experts Large Models) is accepted by IEEE TPAMI, Top Journal, IF=20.4!
- 2026.01: 🎉🎉 Three papers are accepted by ICLR’26! One for Low-bit LLM RL (QeRL: NVFP4 training for parameter-efficient RL) and two papers (LongLive: streaming interactive long-video generation; OmniVinci: a foundation model for omni-LLM) for long-video generation and foundation omni-LLMs. All the codes are opensourced now!
- 2025.10: 🎉🎉 One paper for wearable AI guided glucose management (A Wearable, Dual Closed-loop Insulin Delivery System for Precision Diabetes Management) is accepted by Advanced Materials, Top Interdisciplinary Journal, IF=26.8!
- 2025.09: 🎉🎉 Two papers are accepted by Neurips’25! One for scaling long-video reasoning (Long-RL: Scaling RL to Long Videos) and one for unified reasoning model (Mindomni: Unleashing reasoning generation in vision language models with rgpo). All the codes are opensourced now!
- 2025.05: 🎉🎉 One paper for structural mixed-precision low-bit quantization for LLMs (SliM-LLM) is accepted by ICML’25! All the codes are opensourced now!
- 2025.02: 🎉🎉 One paper for efficient fine-grained chain-of-thought video understanding framework (VideoEspresso) is accepted by CVPR’25, Oral Paper 0.73%! All the codes are opensourced now!
- 2025.01: 🎉🎉 Three papers are accepted by ICLR’25! One for MoE-LLM compression (MC-MoE: MoE-LLM compression) and two papers (InfoMax: data pruning; From-Layers-to-States: dynamic neural network layer) for data efficiency and dynamic neural networks. All the codes are opensourced now!
- 2024.12: 🎉🎉 One Technical Report is accepted by Visual Intelligence
- 2024.05: 🎉🎉 One paper for snn security on rram is accepted by ICCAD’24! All the codes are opensourced now!
- 2024.04: 🎉🎉 One paper for post-training binary quantization of LLMs is accepted by ICML’24! All the codes are opensourced now!
📝 Publications
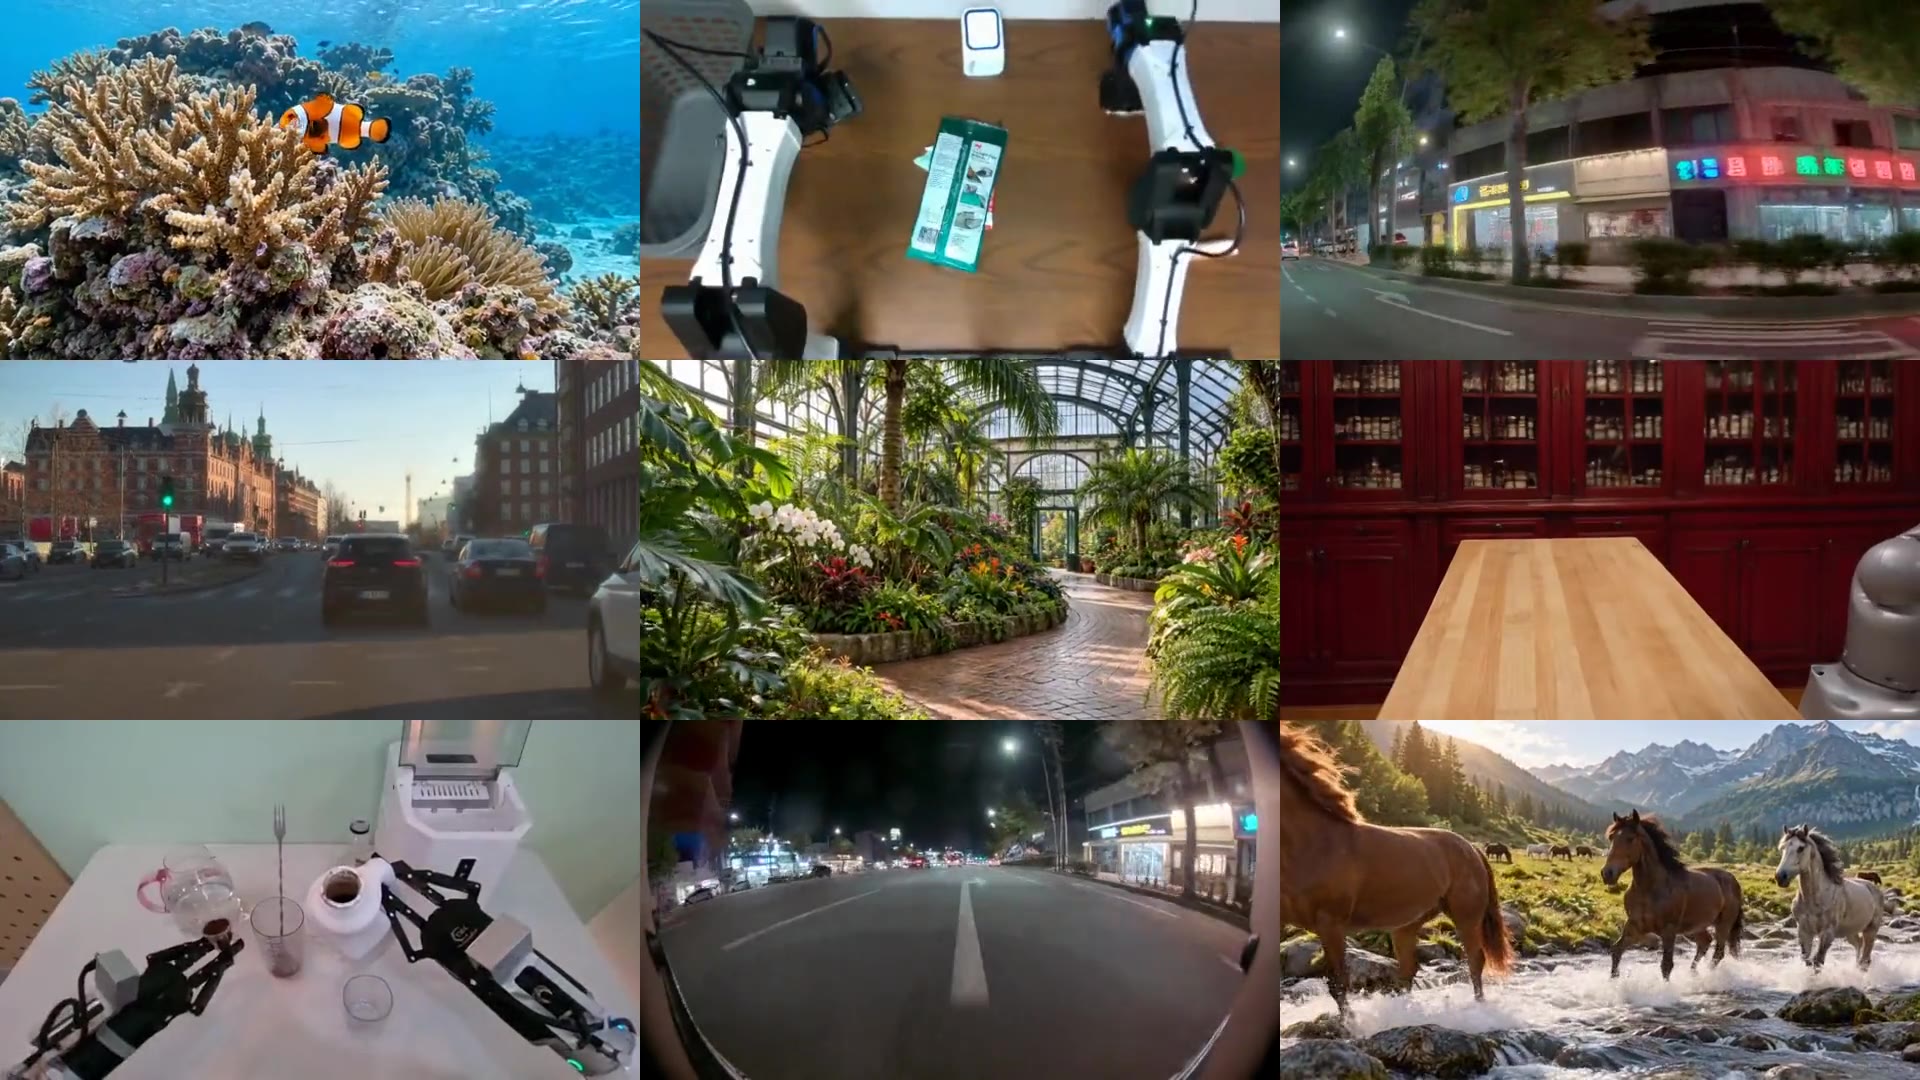
Interactive World Simulation with Cosmos for Physical AI 
NVIDIA Team (Wei Huang is a contributor)
- A shared framework that adapts Cosmos world foundation models into real-time, streaming interactive simulators for Physical AI.
- Supports action-conditioned camera navigation and robot manipulation, controllable video transfer, and synchronized multi-view autonomous-driving simulation.
- Releases open-source code and open-weight Cosmos3-Nano-Sim models for bimanual manipulation, spatial control, and autonomous driving.
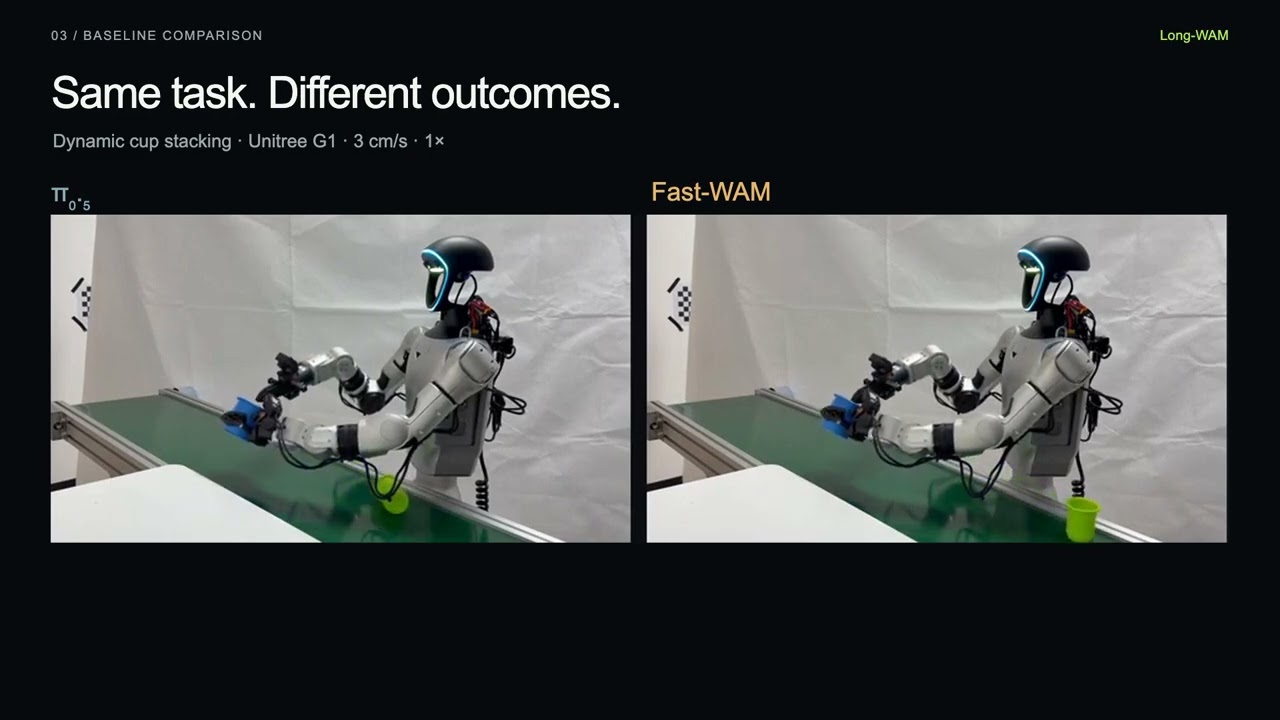
Long-WAM: Scaling the Context of World-Action Models

Wei Huang*, Bohan Zhang*, Chenzhi Liu, Isabella Liu, Shuai Yang, Weian Mao, Luozhou Wang, Yicheng Xiao, Weifeng Lin, Qixin Hu, Bryan Chu, Sifei Liu, Jim (Linxi) Fan, Xiaojuan Qi, Song Han, Yukang Chen
- Long-context world-action modeling with streaming visual memory for real-time robot control.
- Autoregressive video pretraining and context scaling improve long-horizon manipulation across simulation and real robots.
- Streaming observation encoding, asynchronous execution, and hardware acceleration enable real-time deployment on RTX 5090, DGX Spark, and Jetson AGX Thor.
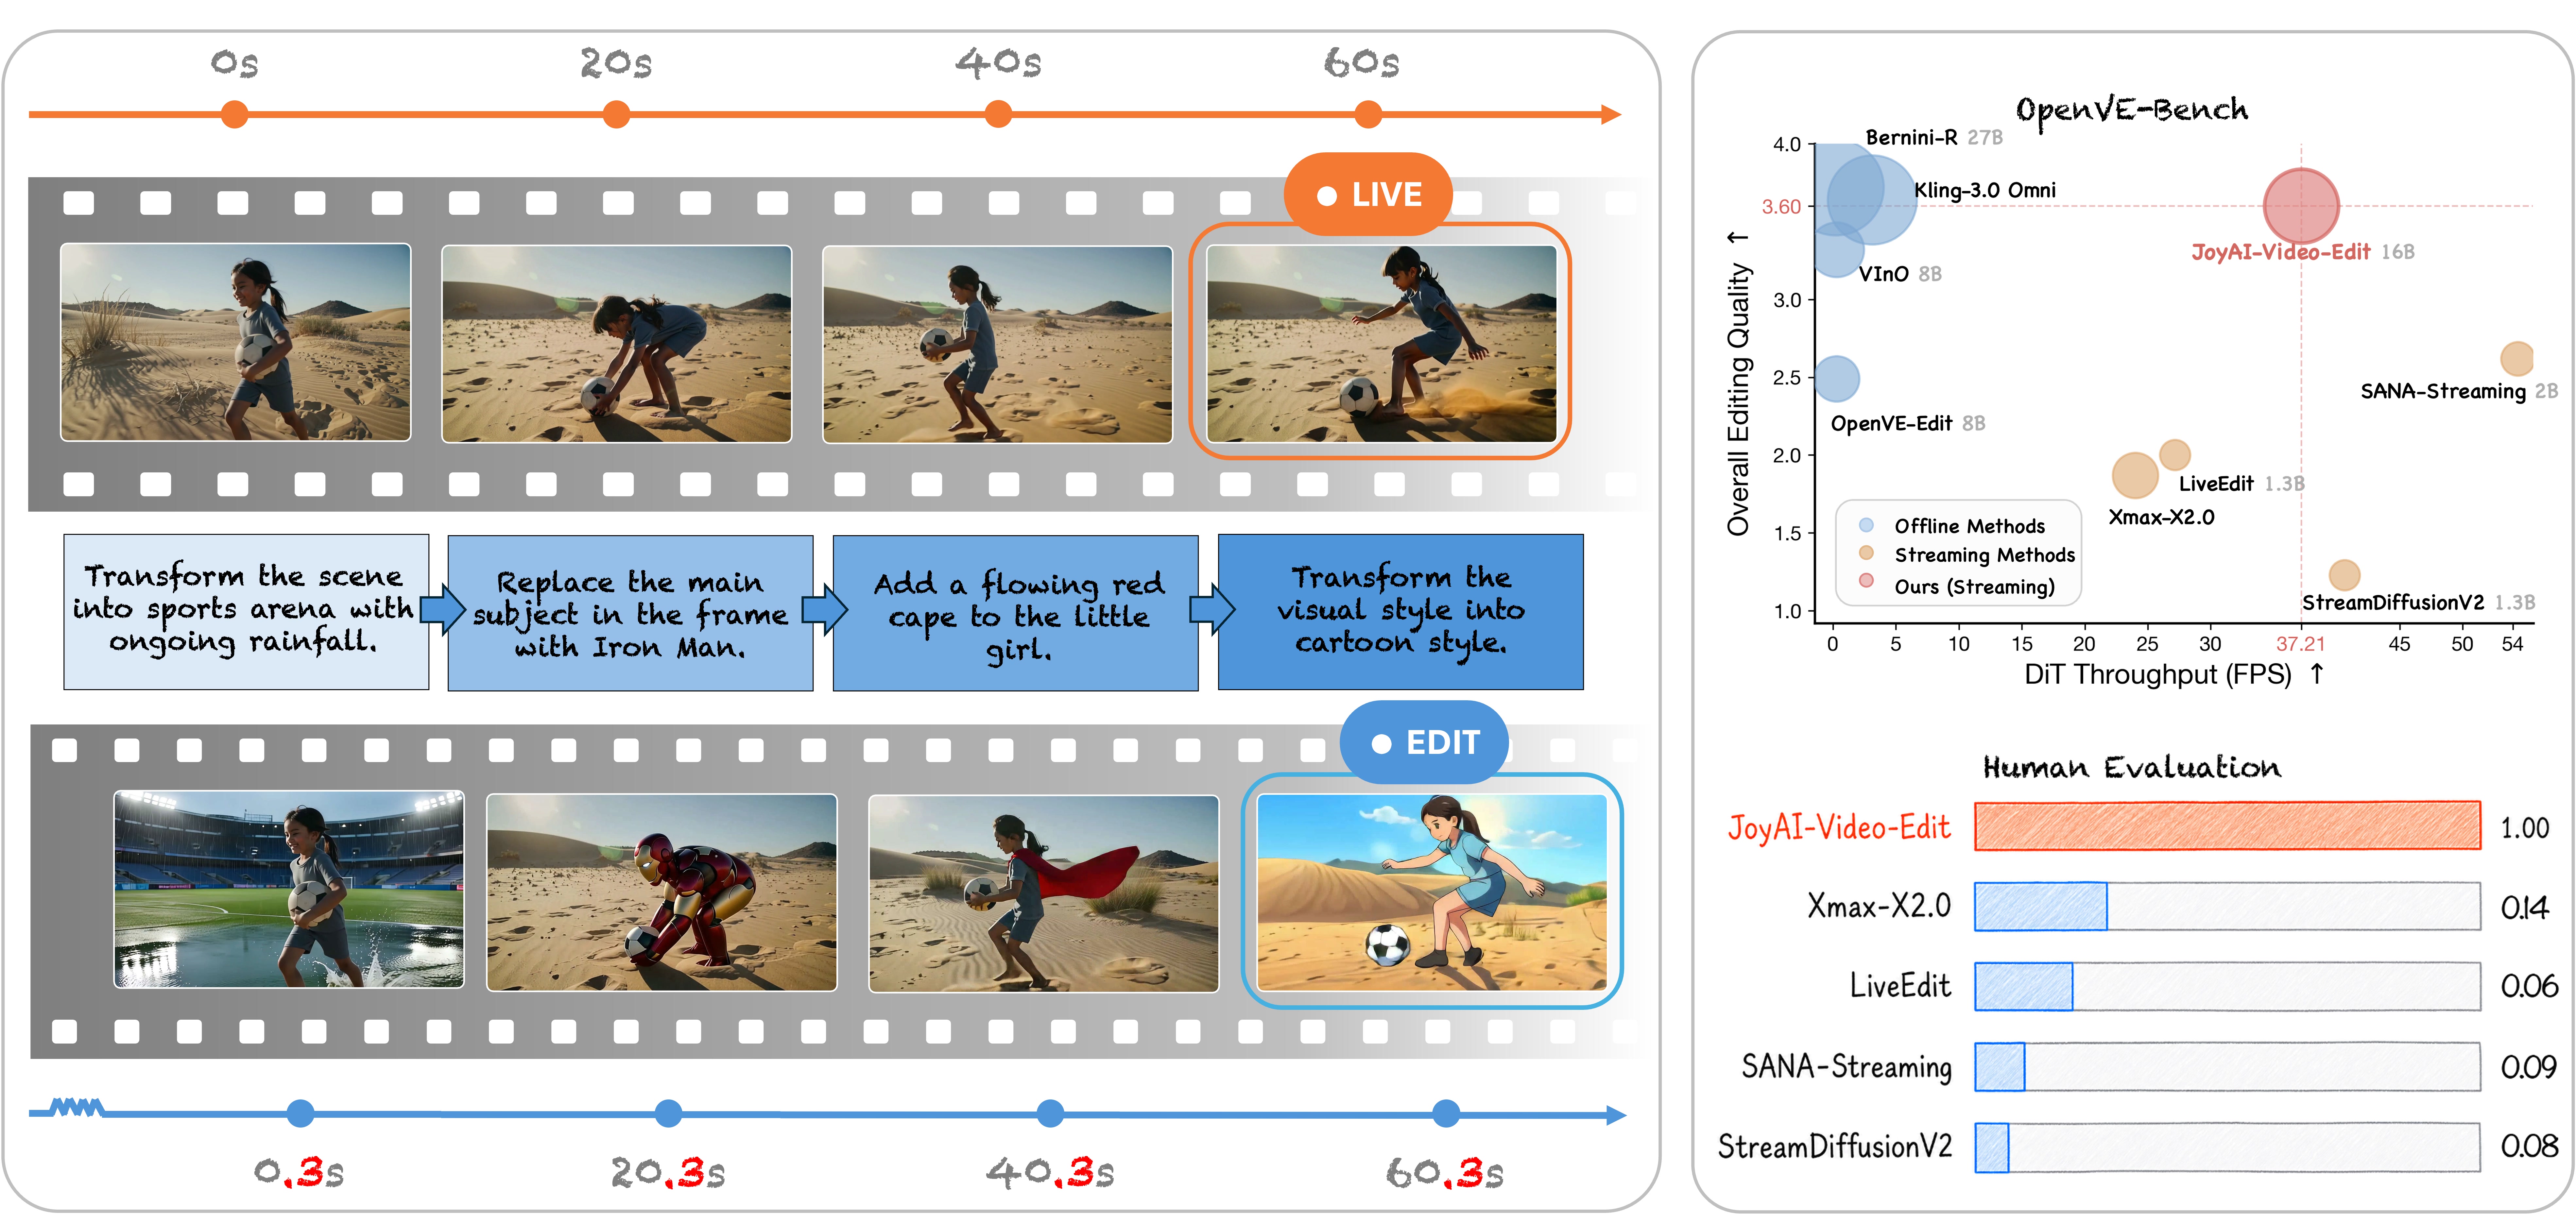
JoyAI-Video-Edit: Real-Time Open-Ended Video Editing with Autoregressive Diffusion 
Yicheng Xiao, Wenxun Dai, Xinran Qin, Lin Song, Maoquan Zhang, Hang Xu, Yukang Chen, Yitong Li, Guohui Zhang, Yuan Zhang, Xuying Zhang, Tommy Zhang, Jianlong Yuan, Peihao Li, Shuai Lu, Siming Fu, Chuyang Zhao, Xin Han, Jie Huang, Wenbo Li, Guoqing Ma, Wei Huang, Xiaojuan Qi, Haoyang Huang, Nan Duan
- Real-time, instruction-guided video editing for open-ended video streams.
- 16B-parameter autoregressive diffusion framework with chunk-wise causal generation and bounded compute.
- End-to-end 720p video editing at approximately 30 FPS on a single NVIDIA B200 GPU.
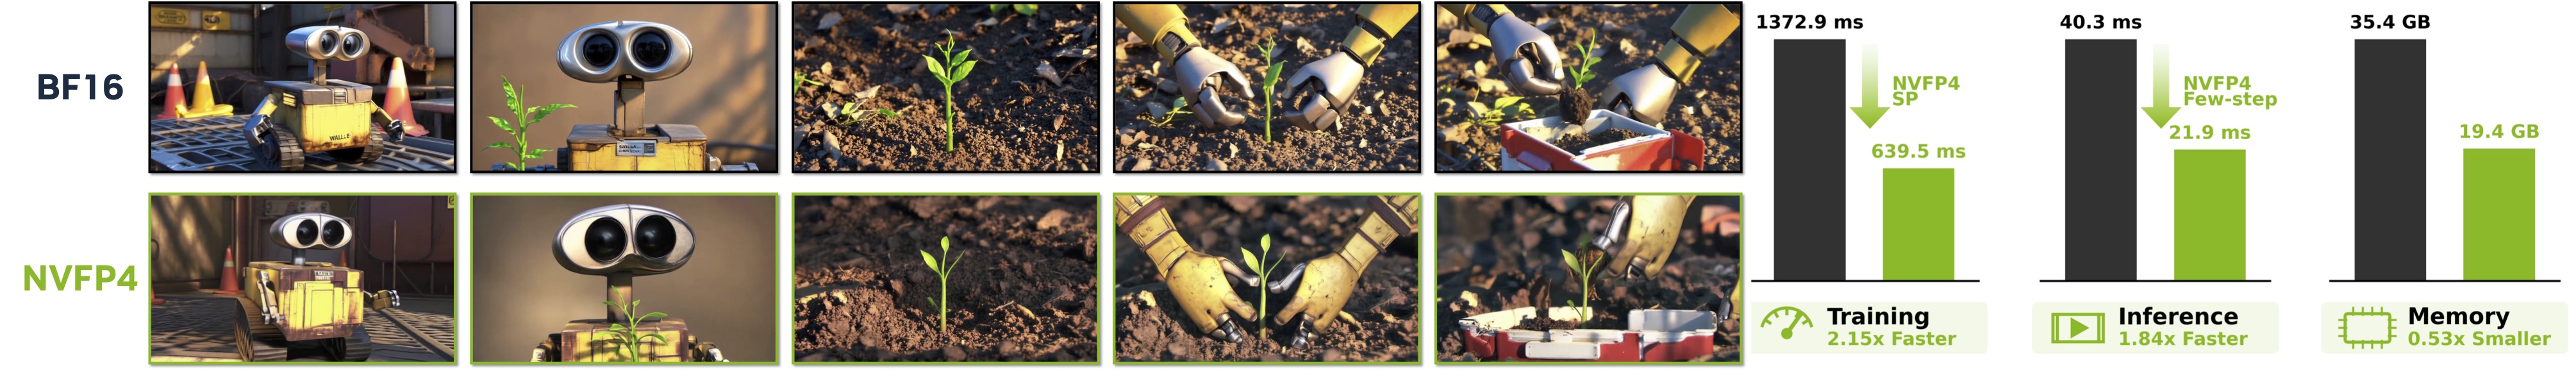
LongLive-2.0: An NVFP4 Parallel Infrastructure for Long Video Generation
Yukang Chen*, Luozhou Wang*, Wei Huang*, Shuai Yang*, Bohan Zhang, Yicheng Xiao, Ruihang Chu, Weian Mao, Qixin Hu, Shaoteng Liu, Yuyang Zhao, Huizi Mao, Ying-Cong Chen, Enze Xie, Xiaojuan Qi, Song Han
- End-to-end NVFP4 parallel infrastructure for long-video generation training and inference.
- Balanced sequence parallel AR training with NVFP4 reduces memory cost and accelerates long-video training.
- W4A4 inference, NVFP4 KV cache, parallel dequantization, and asynchronous VAE decoding enable efficient long-video generation.
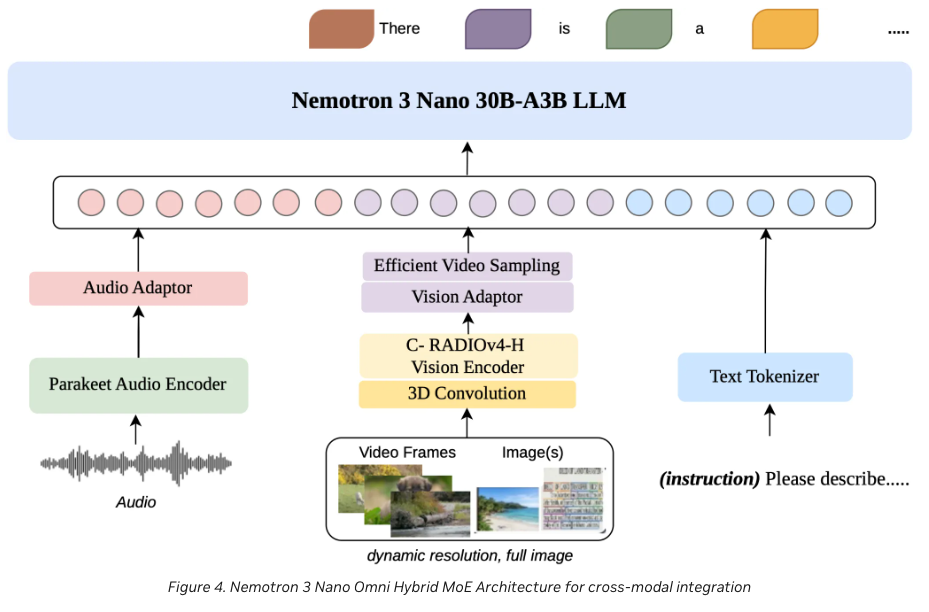
Nemotron 3 Nano Omni: Efficient and Open Multimodal Intelligence 
NVIDIA, including Wei Huang, et al.
- 30B-A3B hybrid Mamba-Transformer MoE for efficient multimodal intelligence.
- Native support for text, image, video, and audio in a unified model.
- Open model checkpoints, training recipes, datasets, and codebase for research and development.
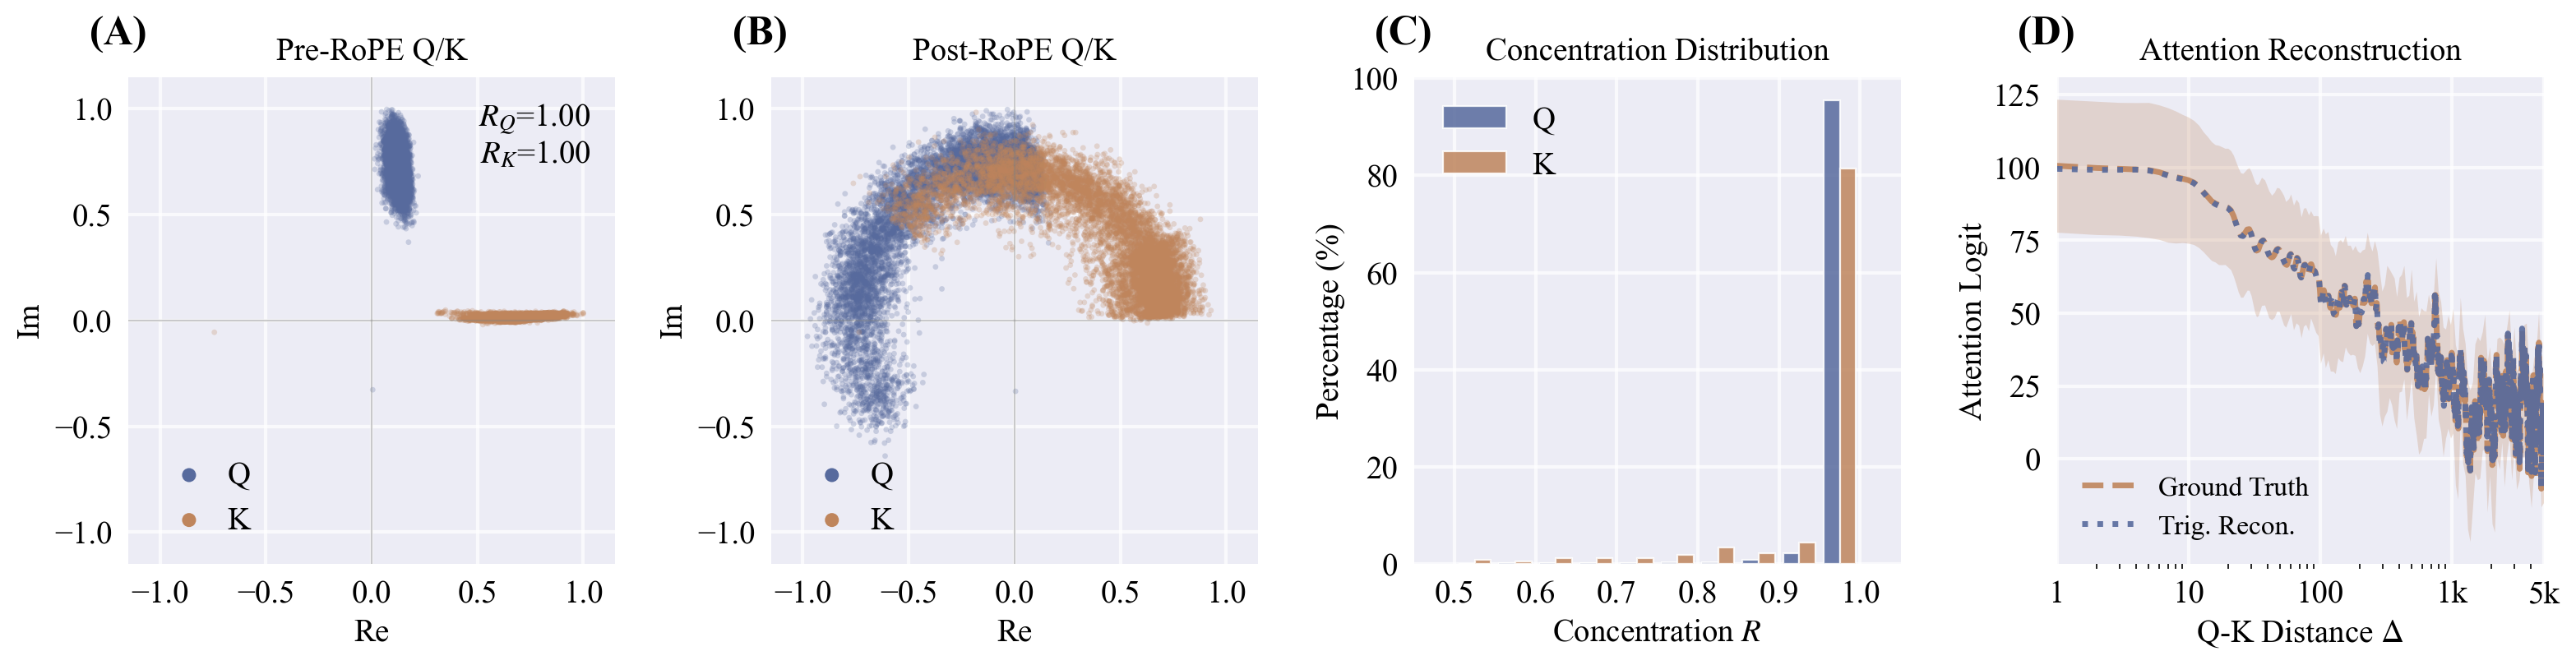
TriAttention: Efficient Long Reasoning with Trigonometric KV Compression 
Weian Mao*, Xi Lin*, Wei Huang*, Yuxin Xie, Tianfu Fu, Bohan Zhuang, Song Han, Yukang Chen
- 2.5x throughput on AIME25 long reasoning while matching Full Attention accuracy (40.8 vs 40.8)
- 10.7x KV memory reduction with trigonometric frequency-domain compression
- OpenClaw compatible — enables local deployment on 24GB RTX 4090
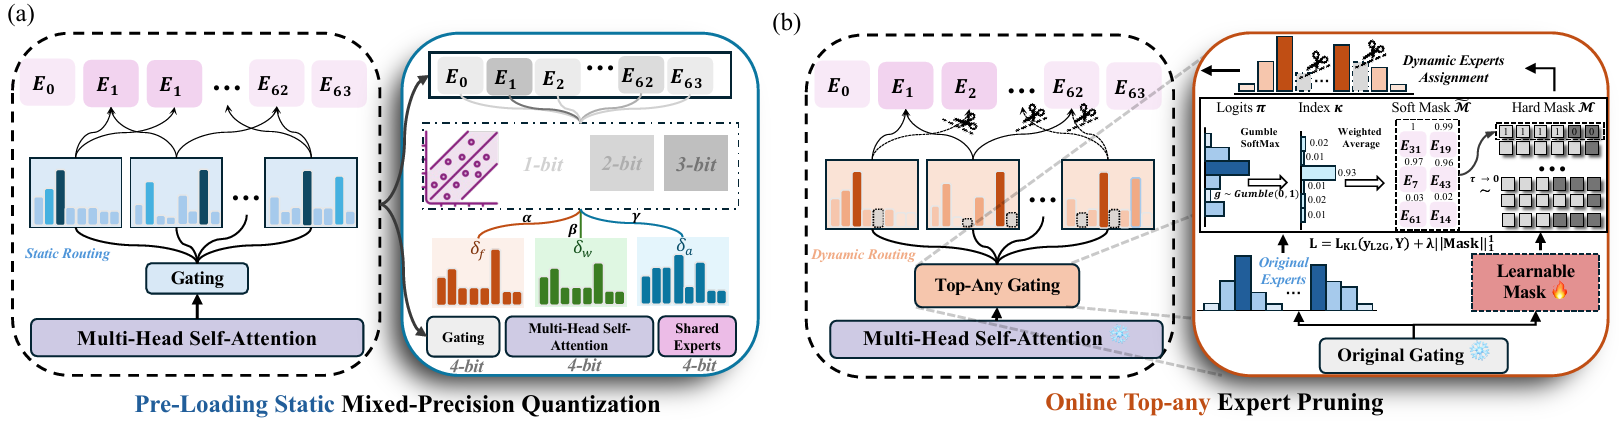
MC#: Mixture Compressor for Mixture-of-Experts Large Models 
Wei Huang, Yue Liao, Yukang Chen, Jianhui Liu, Si Liu, Shiming Zhang, Shuicheng Yan, Xiaojuan Qi
- Accurate weight-only quantization (Weight=1.5~2.5bit) for both MoE-LLMs and MoE-VLMs
- Online Top-any Pruning (OTP) uses Gumbel-Softmax sampling to dynamically select a subset of experts per token
- On DeepSeek-VL2, MC# achieves a 6.2 times weight reduction at 2.57 average bits with only a 1.7% accuracy drop across five multimodal benchmarks. Additionally, OTP reduces expert activation over 20% with less than 1% performance degradation, demonstrating strong potential for efficient MoE-based model deployment.
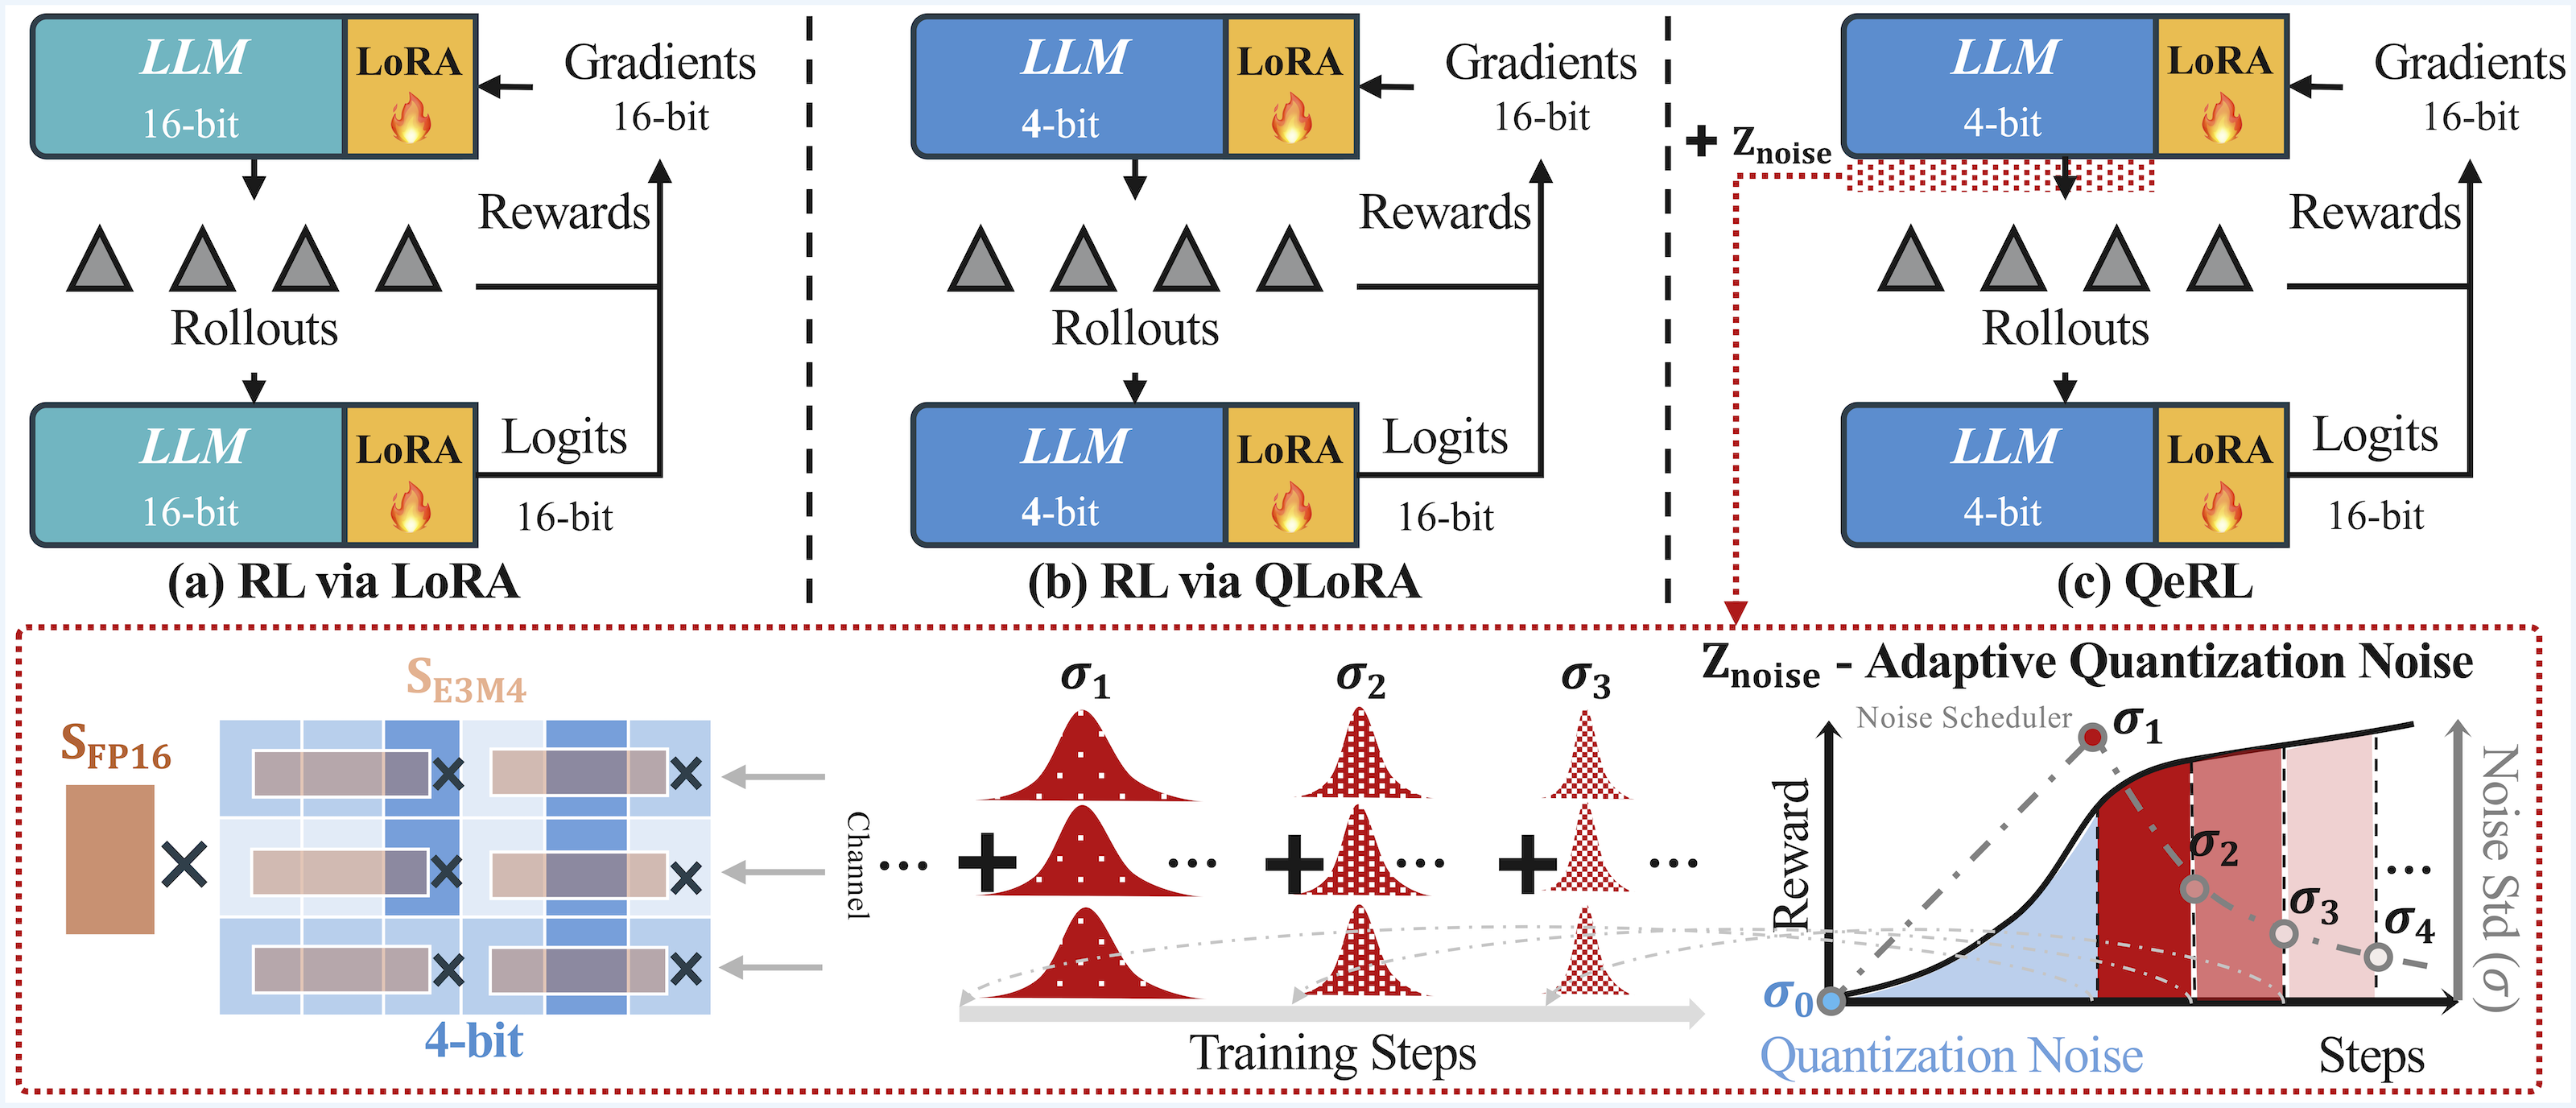
QeRL: Beyond Efficiency – Quantization-enhanced Reinforcement Learning for LLMs 
Wei Huang, Yi Ge, Shuai Yang, Yicheng Xiao, Huizi Mao, Yujun Lin, Hanrong Ye, Sifei Liu, Ka Chun Cheung, Hongxu Yin, Yao Lu, Xiaojuan Qi, Song Han, Yukang Chen
- 🧠 4-bit quantized RL training.
- 💪 Train a 32B LLM on a single H100 GPU.
- 🎯 Accuracy on par with bfloat16-level accuracy.
- 🔥 Supports NVFP4 quantization format.
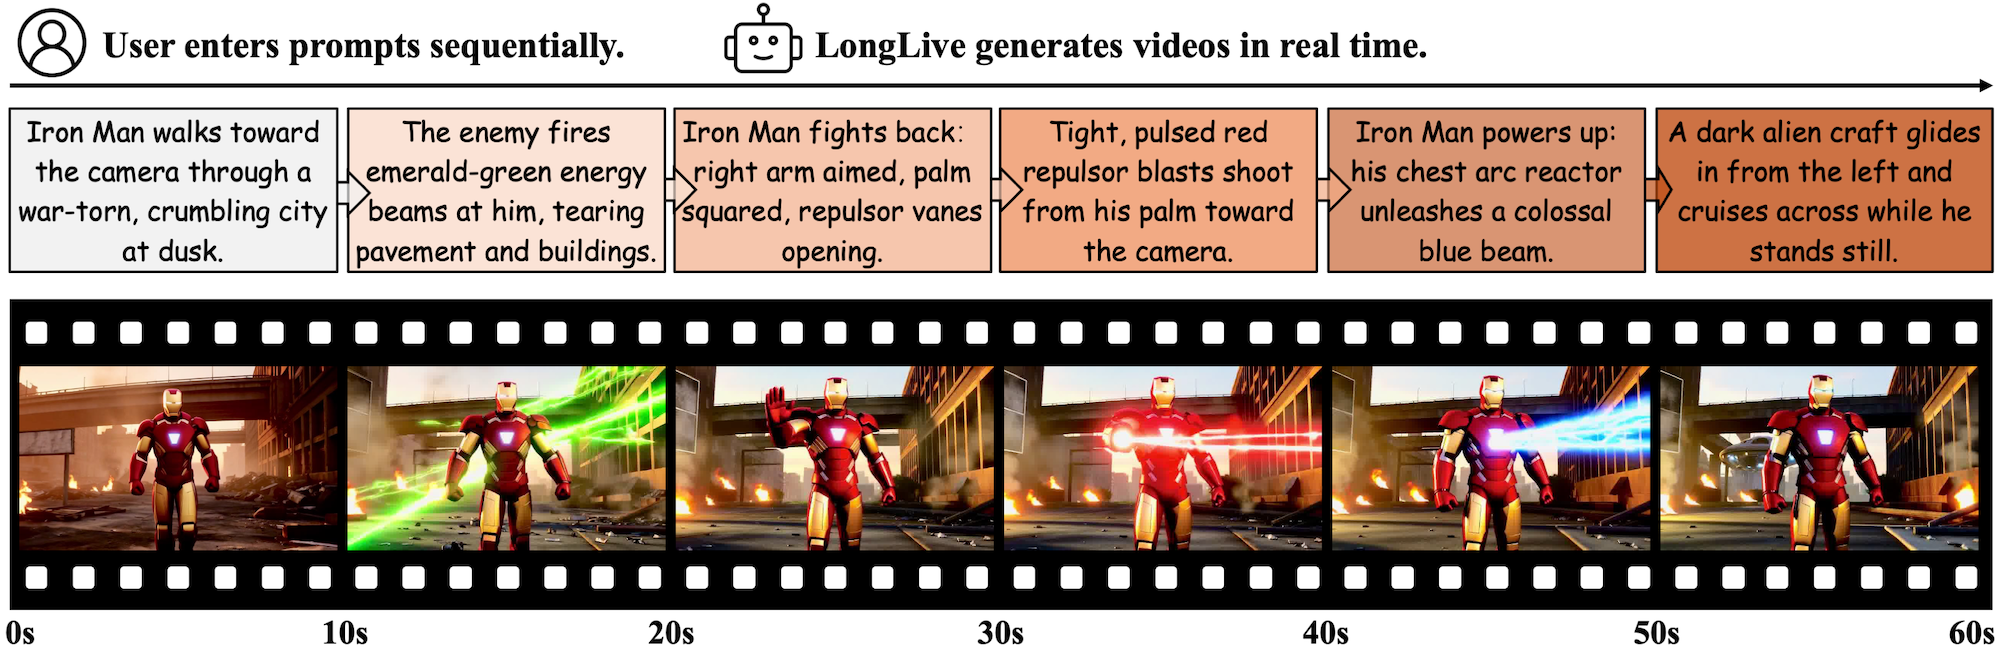
LongLive: Real-time Interactive Long Video Generation
Shuai Yang, Wei Huang, Ruihang Chu, Yicheng Xiao, Yuyang Zhao, Xianbang Wang, Muyang Li, Enze Xie, Yingcong Chen, Yao Lu, Song Han, Yukang Chen
- Generates video in real time as users enter text prompts.
- 20.7 FPS on a single H100, up to 240s per clip. Fine-tunes SOTA short-video models (e.g., Wan) into long-video generators.
- One step closer to World Models.
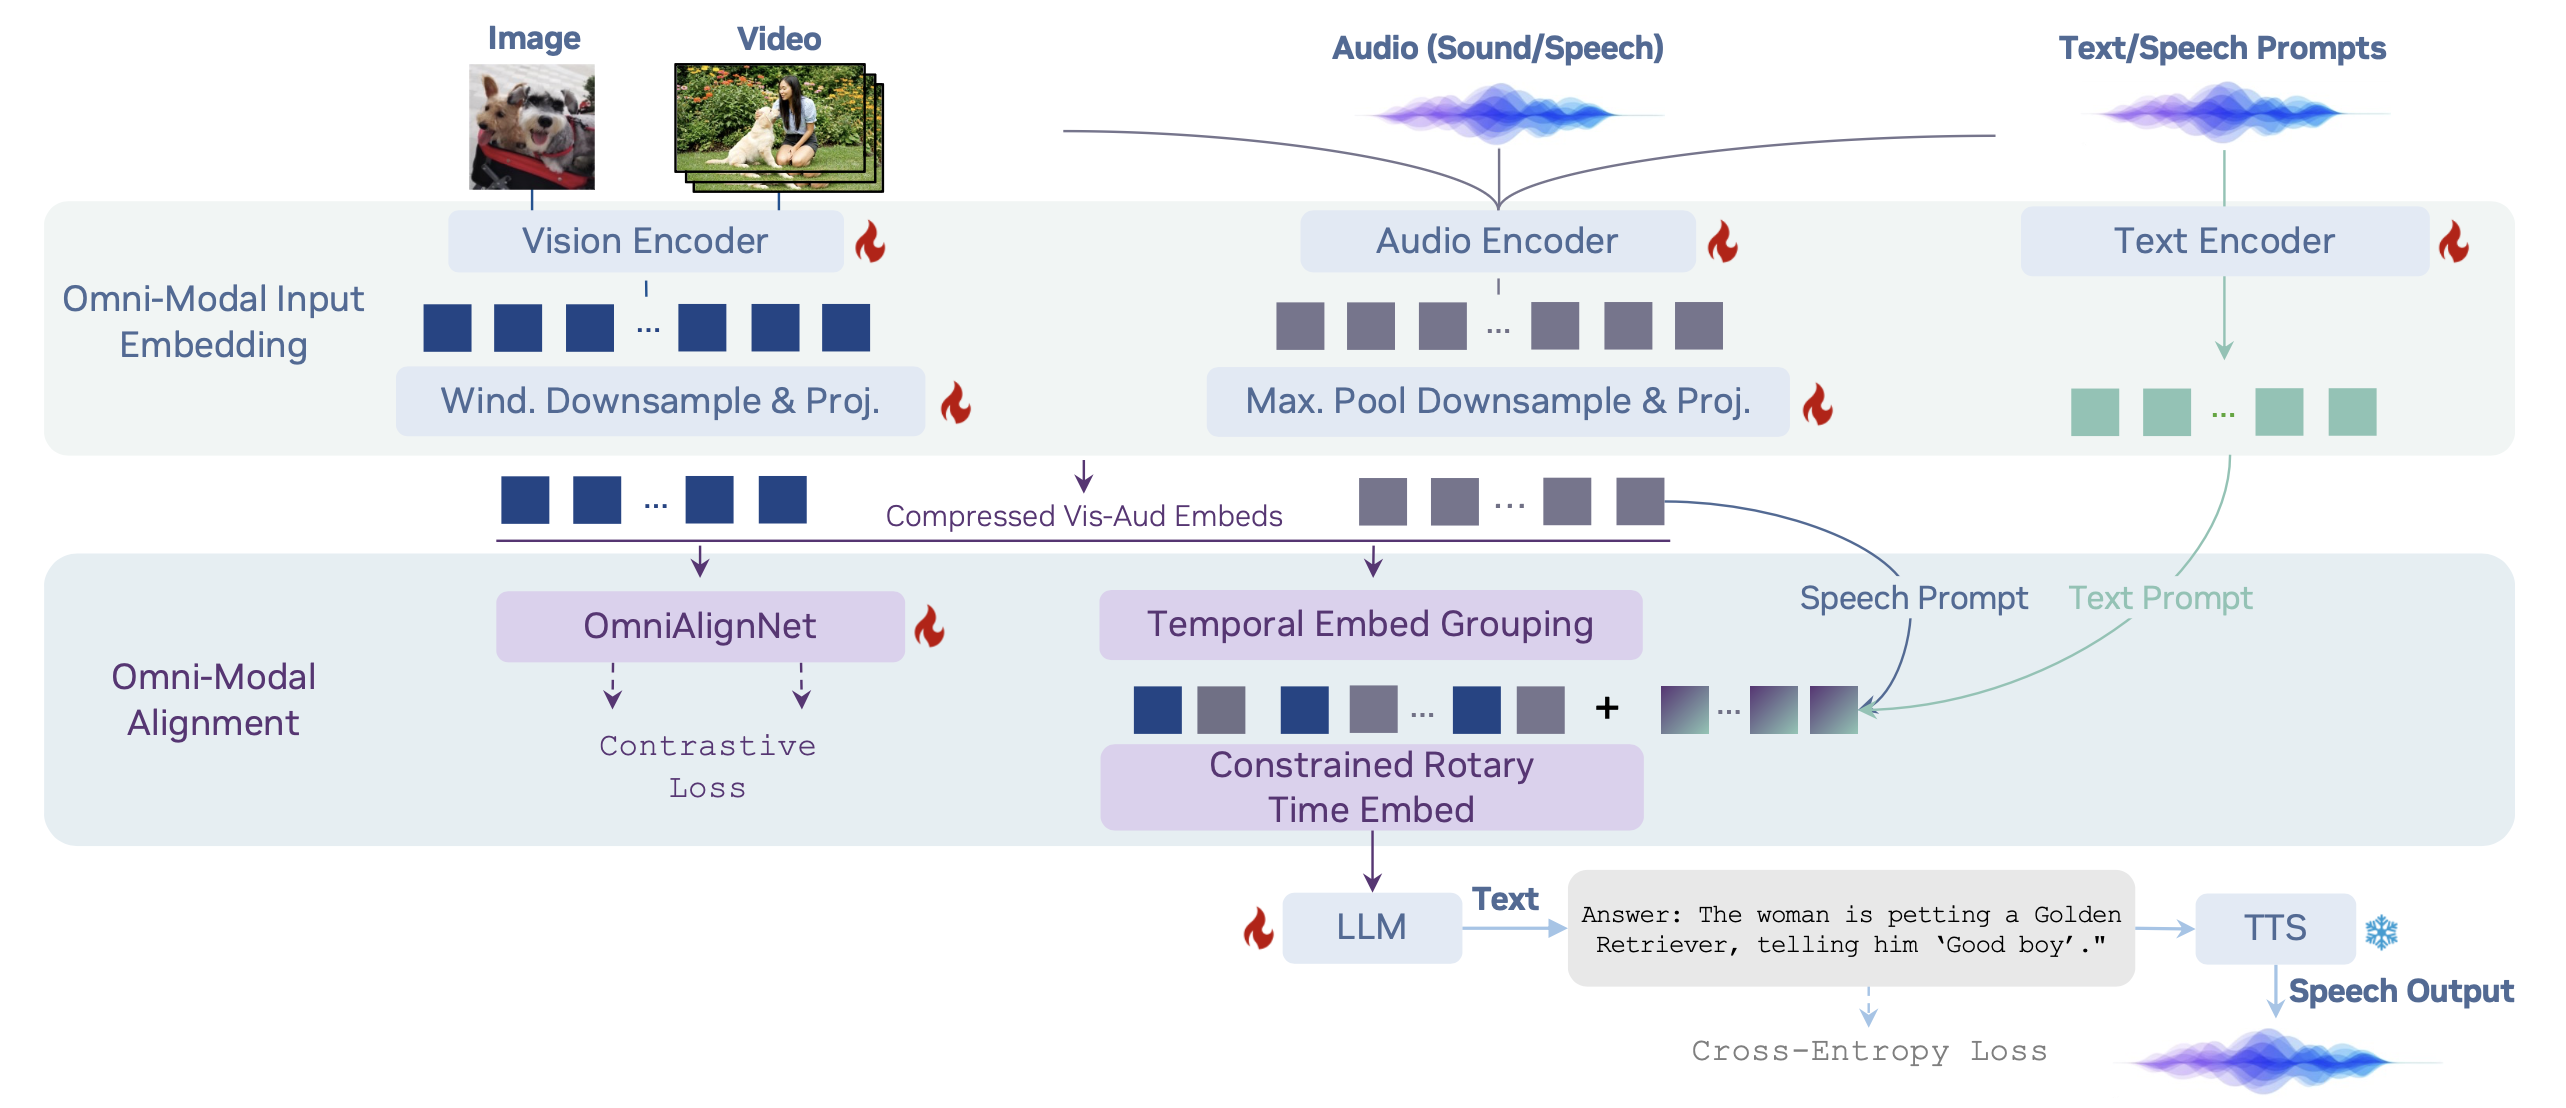
OmniVinci: Enhancing Architecture and Data for Omni-Modal Understanding LLM 
Hanrong Ye*, Chao-Han Huck Yang*, Arushi Goel*,Wei Huang*, Ligeng Zhu*, Yuanhang Su*, Sean Lin*, An-Chieh Cheng*, Zhen Wan*, Jinchuan Tian*, Yuming Lou*, Dong Yang*, Zhijian Liu, Yukang Chen, Ambrish Dantrey, Ehsan Jahangiri, Sreyan Ghosh, Daguang Xu, Ehsan Hosseini Asl, Danial Mohseni Taheri, Vidya Murali, Sifei Liu, Yao Lu, Oluwatobi Olabiyi, Yu-Chiang Frank Wang, Rafael Valle, Bryan Catanzaro, Andrew Tao, Song Han, Jan Kautz, Hongxu Yin*, Pavlo Molchanov*
- OmniAlignNet for strengthening alignment between vision and audio embeddings in a shared omni-modal latent space.
- emporal Embedding Grouping for capturing relative temporal alignment between vision and audio signals.
- Constrained Rotary Time Embedding for encoding absolute temporal information in omni-modal embeddings. We introduce a curation and synthesis pipeline that generates 24M single-modal and omni-modal conversations.
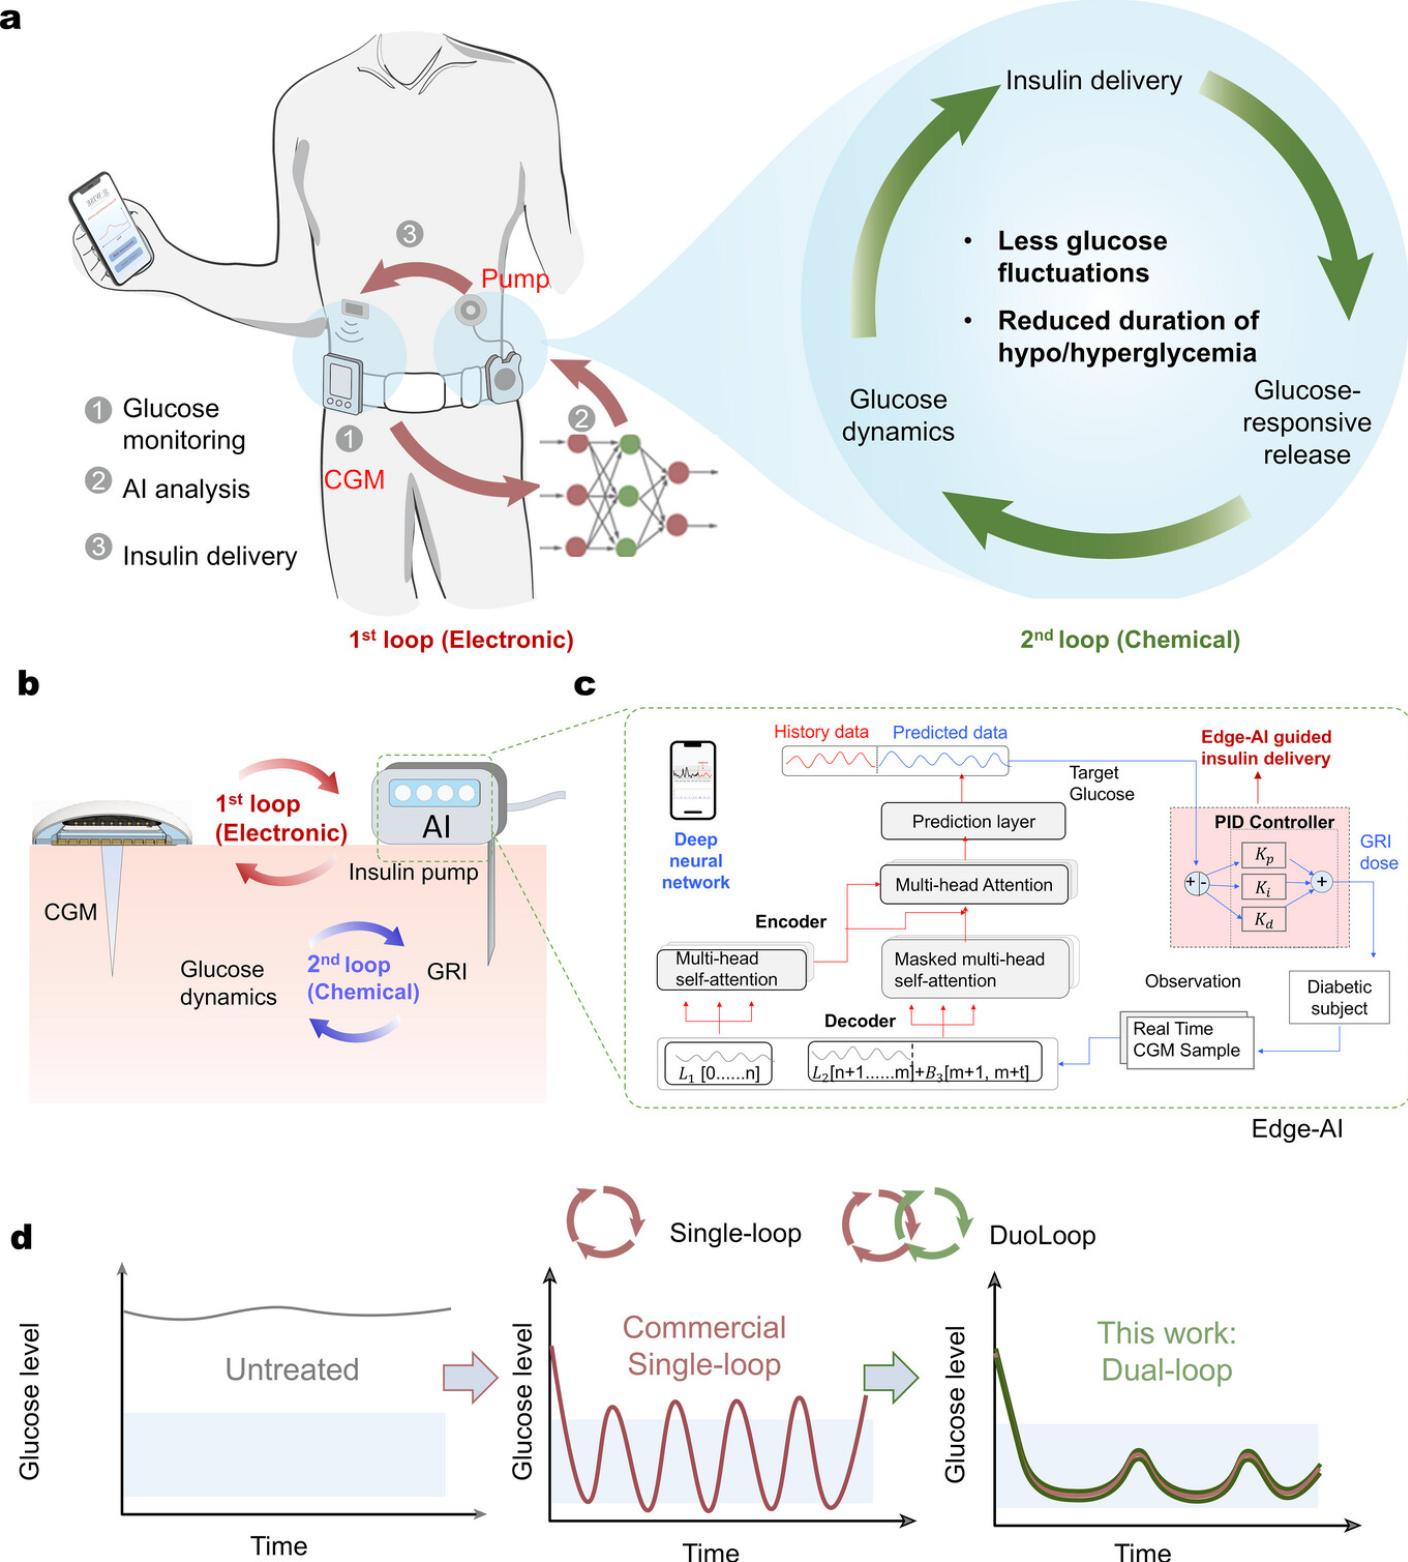
A Wearable, Dual Closed-loop Insulin Delivery System for Precision Diabetes Management
Xuecheng He*, Wei Huang*, Wensheng Lin, Binbin Cui, Xinyu Tian, Jing Bai, Dingyao Liu, Ivo Pang, Hao Huang, Shixian Lin, Jixiang Zhu, Jinqiang Wang, Shiming Zhang
- We have presented a wearable DuoLoop insulin delivery system to address the safety issues associated with traditional single closed-loop ones.
- The 1st closed-loop system automates insulin delivery through wearable CGMs. The 2nd closed-loop system involves the GRI, where the insulin release rate depends on real-time in vivo glucose levels.
- To link the two sections, an AI algorithm was developed by training on extensive glucose data sets, which enables accurate predictions and guides GRI delivery at optimal dosage and timing.
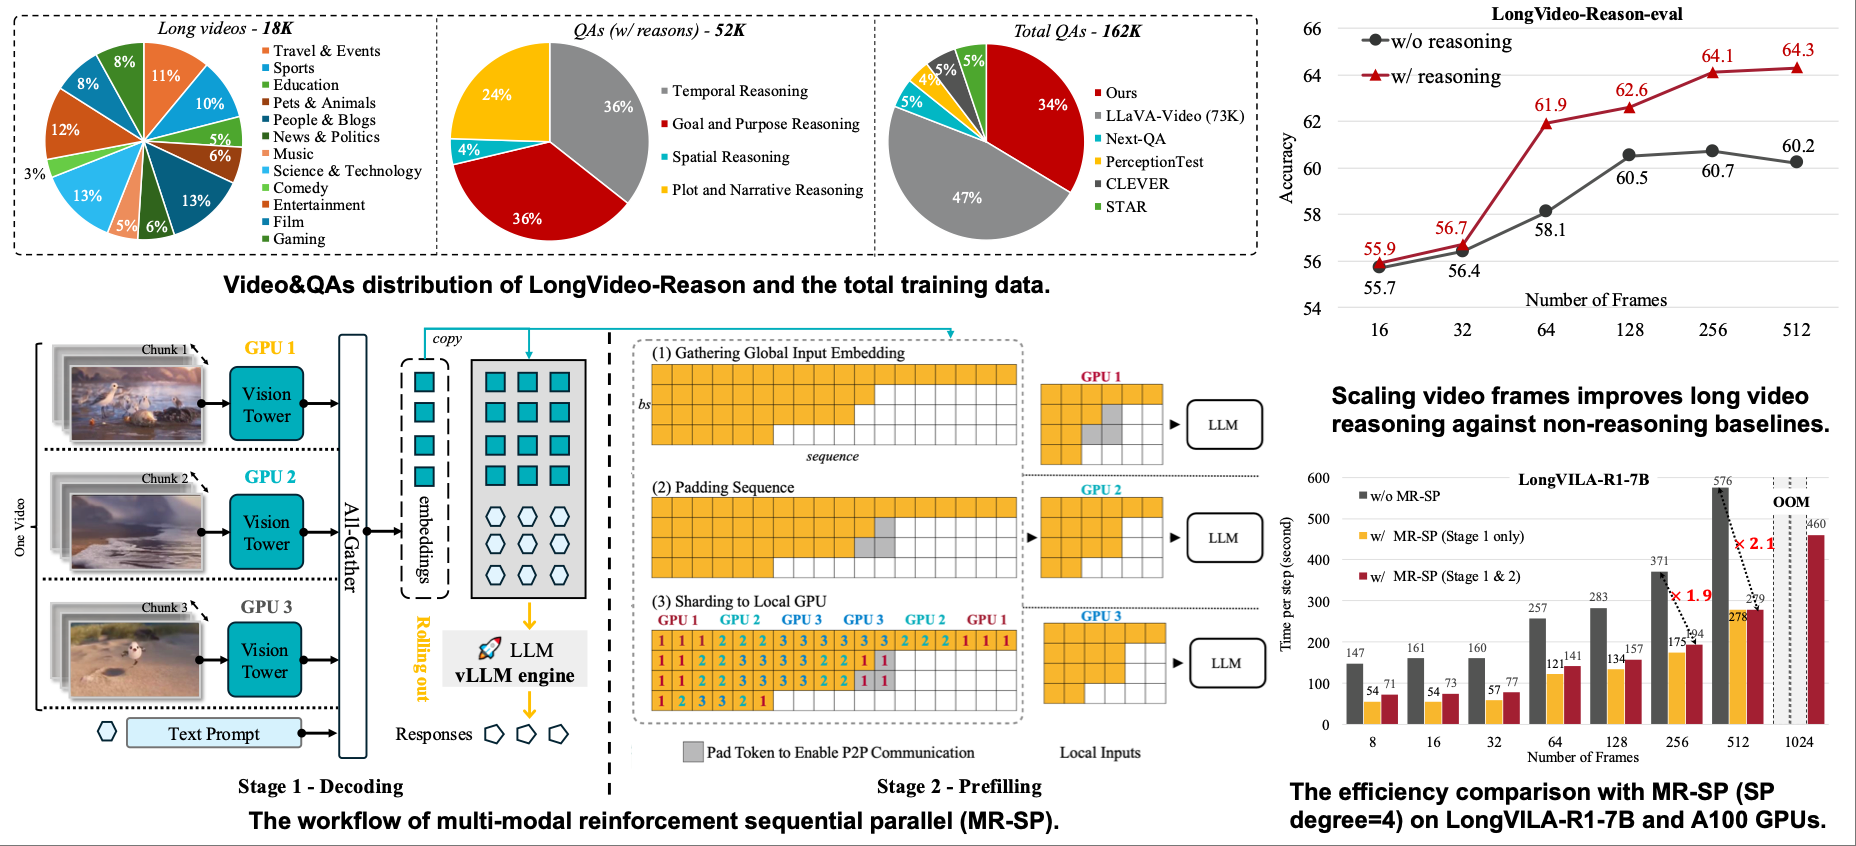

Yukang Chen*, Wei Huang*, Baifeng Shi, Qinghao Hu, Hanrong Ye, Ligeng Zhu, Zhijian Liu, Pavlo Molchanov, Jan Kautz, Xiaojuan Qi, Sifei Liu, Hongxu Yin, Yao Lu, Song Han
- MR-SP infrastructure with sequence parallelism and vLLM-based cached-embedding rollouts, enabling up to 8,192 frames, hour-long RL on 8×A100, 2.1× speedup, and strong results (VideoMME 65.1% no subs, 71.1% with subs) via LongVILA-R1-7B.
- Two-stage pipeline combining CoT-SFT and RL to scale reasoning for long-horizon video understanding.
- LongVideo-Reason (104K long-video QA pairs) with high-quality chain-of-thought annotations across diverse domains.
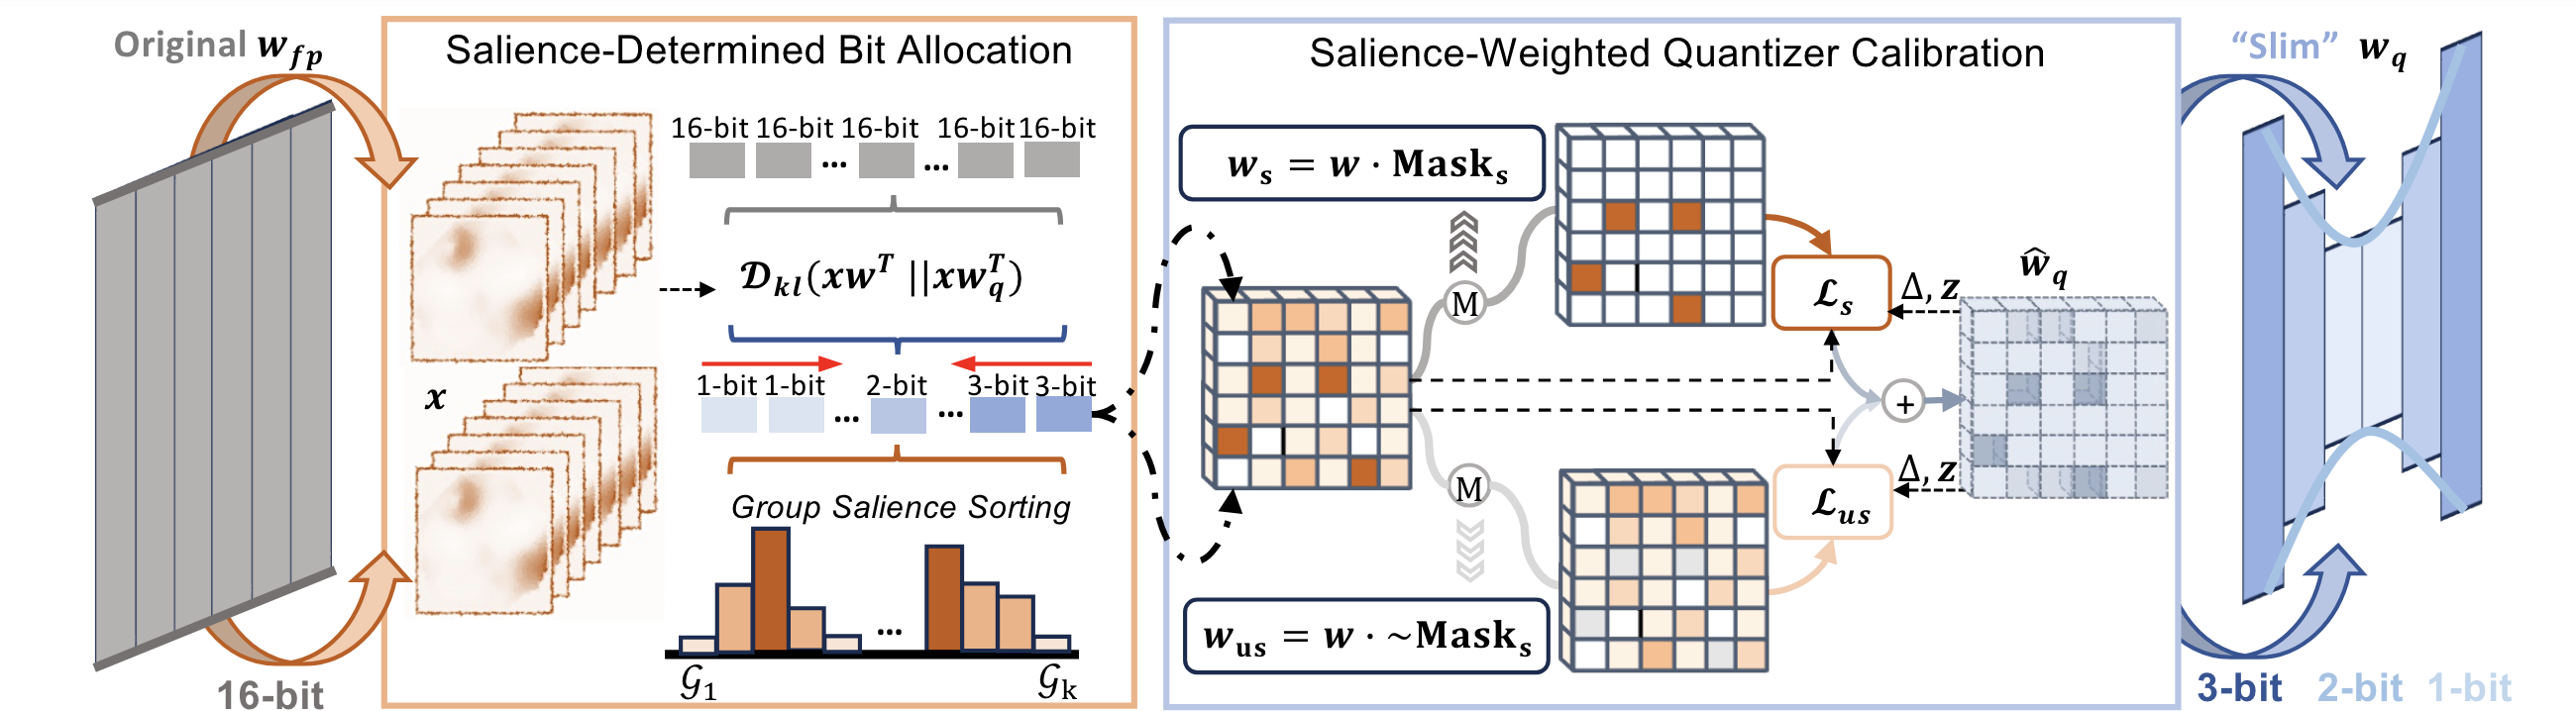
SliM-LLM: Salience-Driven Mixed-Precision Quantization for Large Language Models 
Wei Huang, Haotong Qin, Yangdong Liu, Yawei Li, Qinshuo Liu, Xianglong Liu, Luca Benini, Michele Magno, Shiming Zhang, Xiaojuan Qi
- A novel scheme that observes and proves the structure-clustering of salient elements in LLMs weight matrix.
- The first group-wise mixed-precision quantization framework for LLMs.
- Serve as a plug-and-play approach to GPTQ/Omniquant/…, improving the inference-friendly method under low-bit quantization.
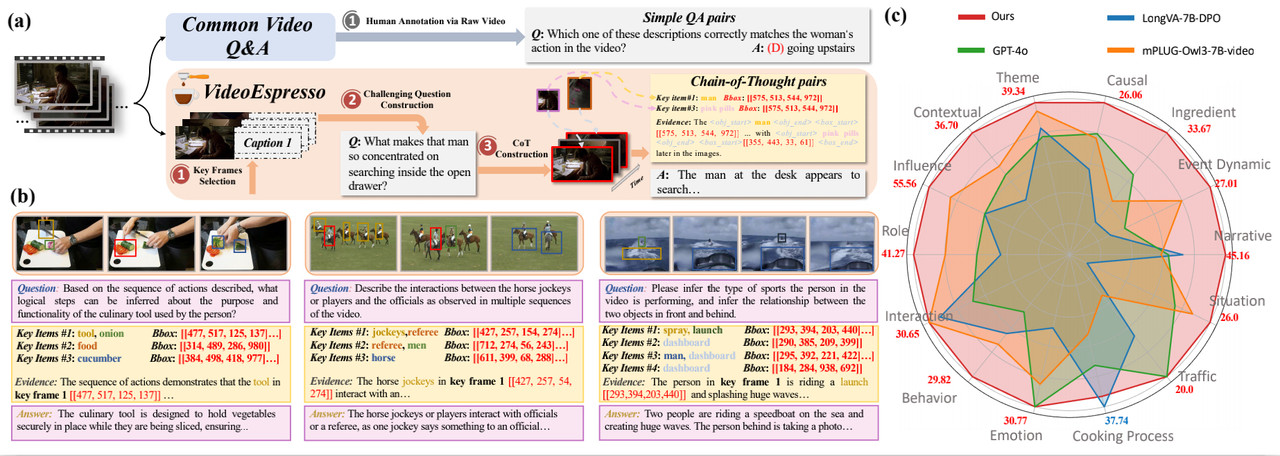

Songhao Han, Wei Huang, Hairong Shi, Le Zhuo, Xiu Su, Shifeng Zhang, Xu Zhou, Xiaojuan Qi, Yue Liao, Si Liu
- A novel dataset designed to enhance video reasoning by addressing the limitations of existing datasets in terms of scale and granularity.
- We proposed a Hybrid LVLMs Collaboration framework achieving cost-effective and accurate video reasoning, outperforming baseline models on the majority of tasks across our proposed benchmark.
- VideoEspresso sets a new starting point in video reasoning, offering rich annotations that facilitate advanced multimodal understanding.
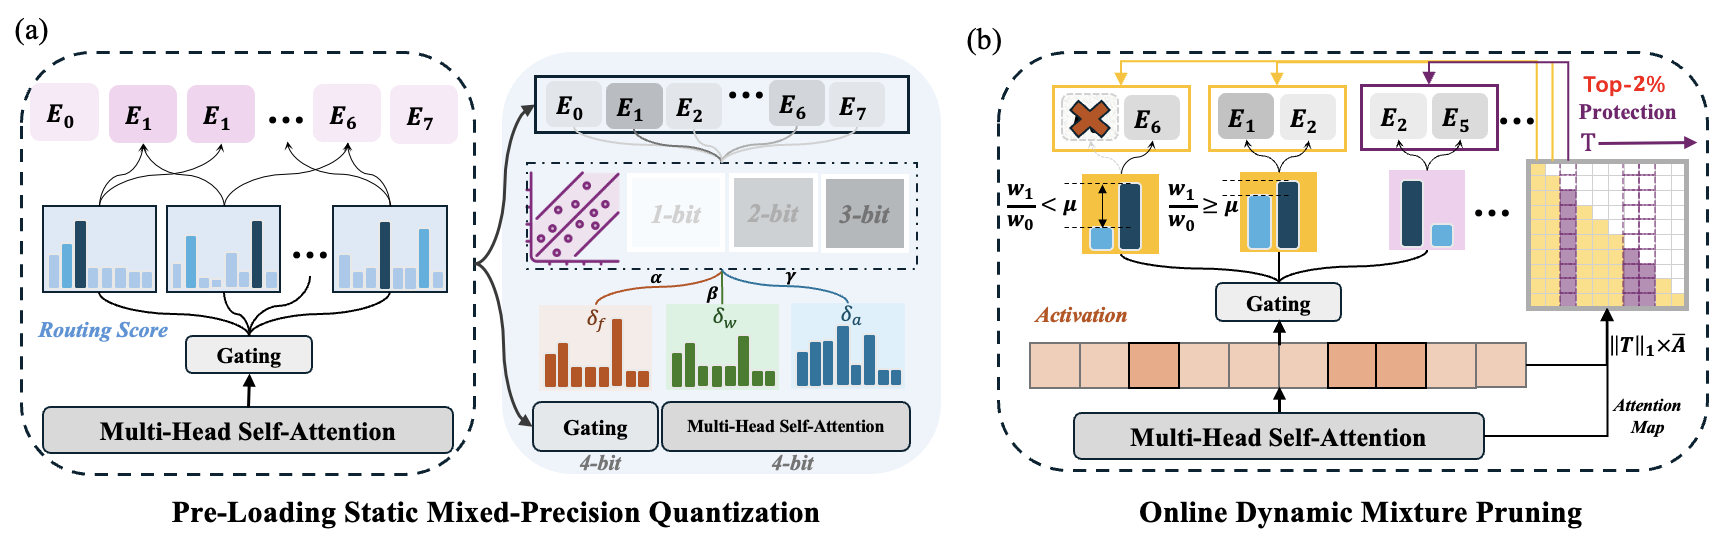
MC-MoE: Mixture Compressor for Mixture-of-Experts LLMs Gains More
Wei Huang, Yue Liao, Jianhui Liu, Ruifei He, Haoru Tan, Shiming Zhang, Hongsheng Li, Si Liu, Xiaojuan Qi
- MC-MoE for accurate weight-only quantization (Weight=1.5~2.5bit).
- MC-MoE for efficient online dynamic pruning (additional compression ratio > 10%)
- MC-MoE integrates static quantization and dynamic pruning to collaboratively achieve extreme compression for MoE-LLMs with less accuracy loss, ensuring an optimal trade-off between performance and efficiency.
- For instance, at 2.54 bits, MC-MoE compresses 76.6% of the model, with only a 3.8% average accuracy loss. During dynamic inference, we further reduce activated parameters by 15%, with a performance drop of less than 0.6%.
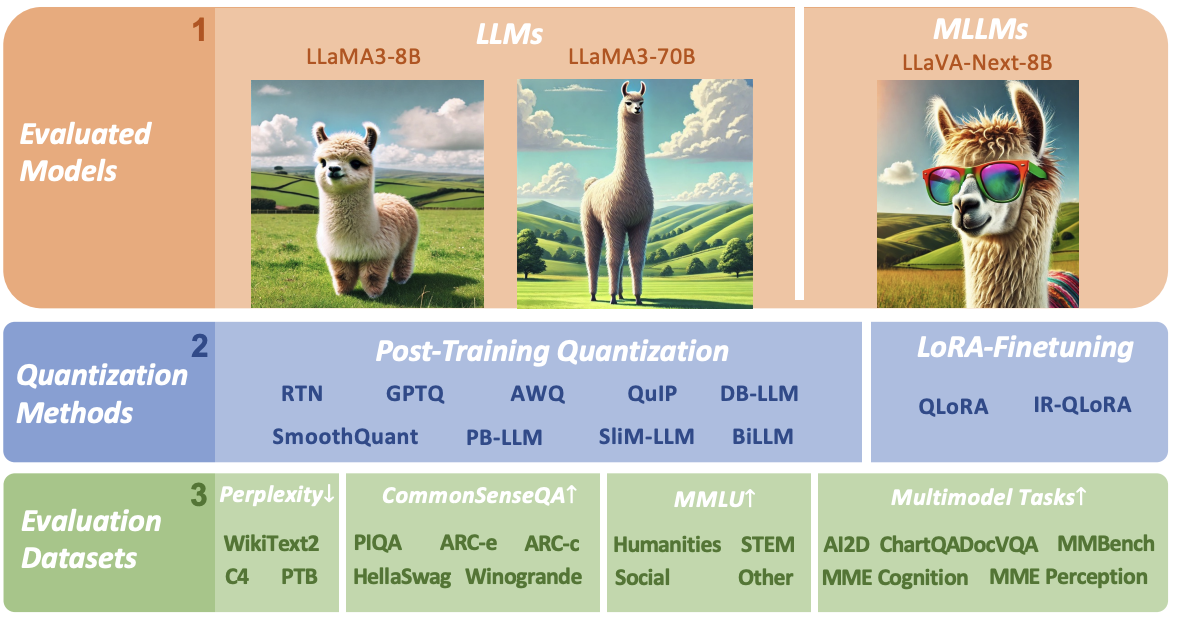
An Empirical Study of LLaMA3 Quantization: From LLMs to MLLMs 
Wei Huang, Xingyu Zheng, Xudong Ma, Haotong Qin, Chengtao Lv, Hong Chen, Jie Luo, Xiaojuan Qi, Xianglong Liu, Michele Magno
- Explore the performance of LLaMA3 series models under existing post-training quantization and LoRA-finetuning methods.
- Point out the significant performance loss of MLLMs based on LLaMA3 under low-bit post-training quantization.
- Highlights the significant performance gap under low bit-width that needs to be bridged in future developments.
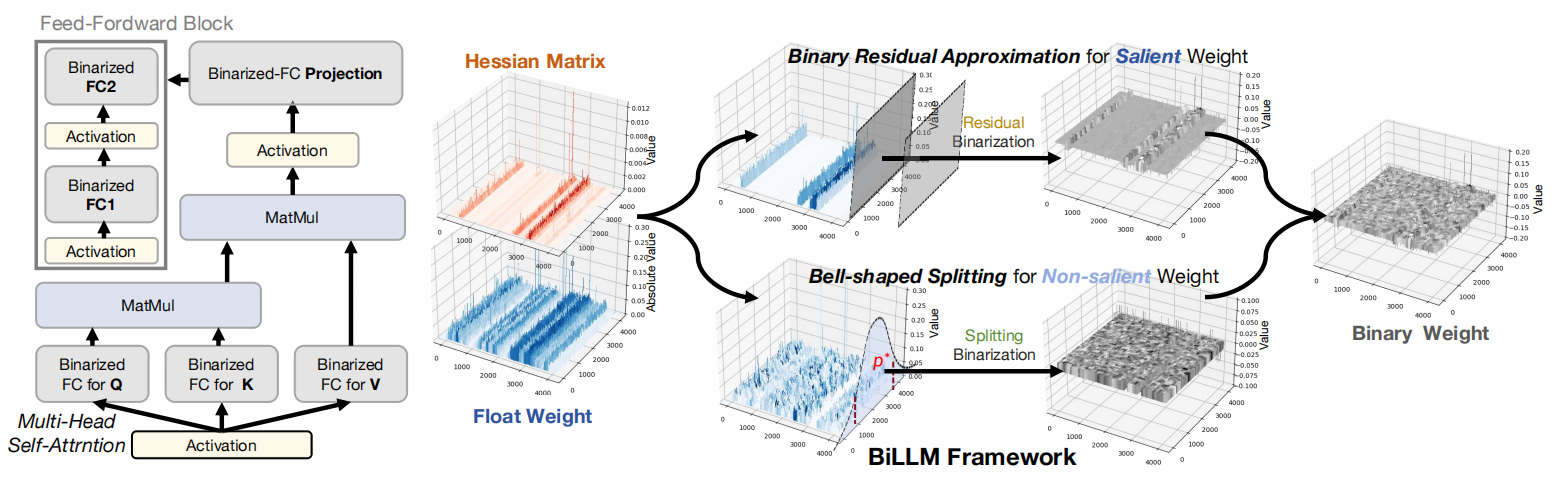
BiLLM: Pushing the Limit of Post-Training Quantization for LLMs 
Wei Huang, Yangdong Liu, Haotong Qin, Ying Li, Shiming Zhang, Xianglong Liu, Michele Magno, Xiaojuan Qi
- Compress LLM weights to as low as 1.08-1.1 bit and exceeds the performance of previous quantization methods at 2-bit or even 3-bit.
- Implements high-performance binary LLM in PTQ mode, efficiently achieving 1bit LLM compression without additional training and backpropagation.
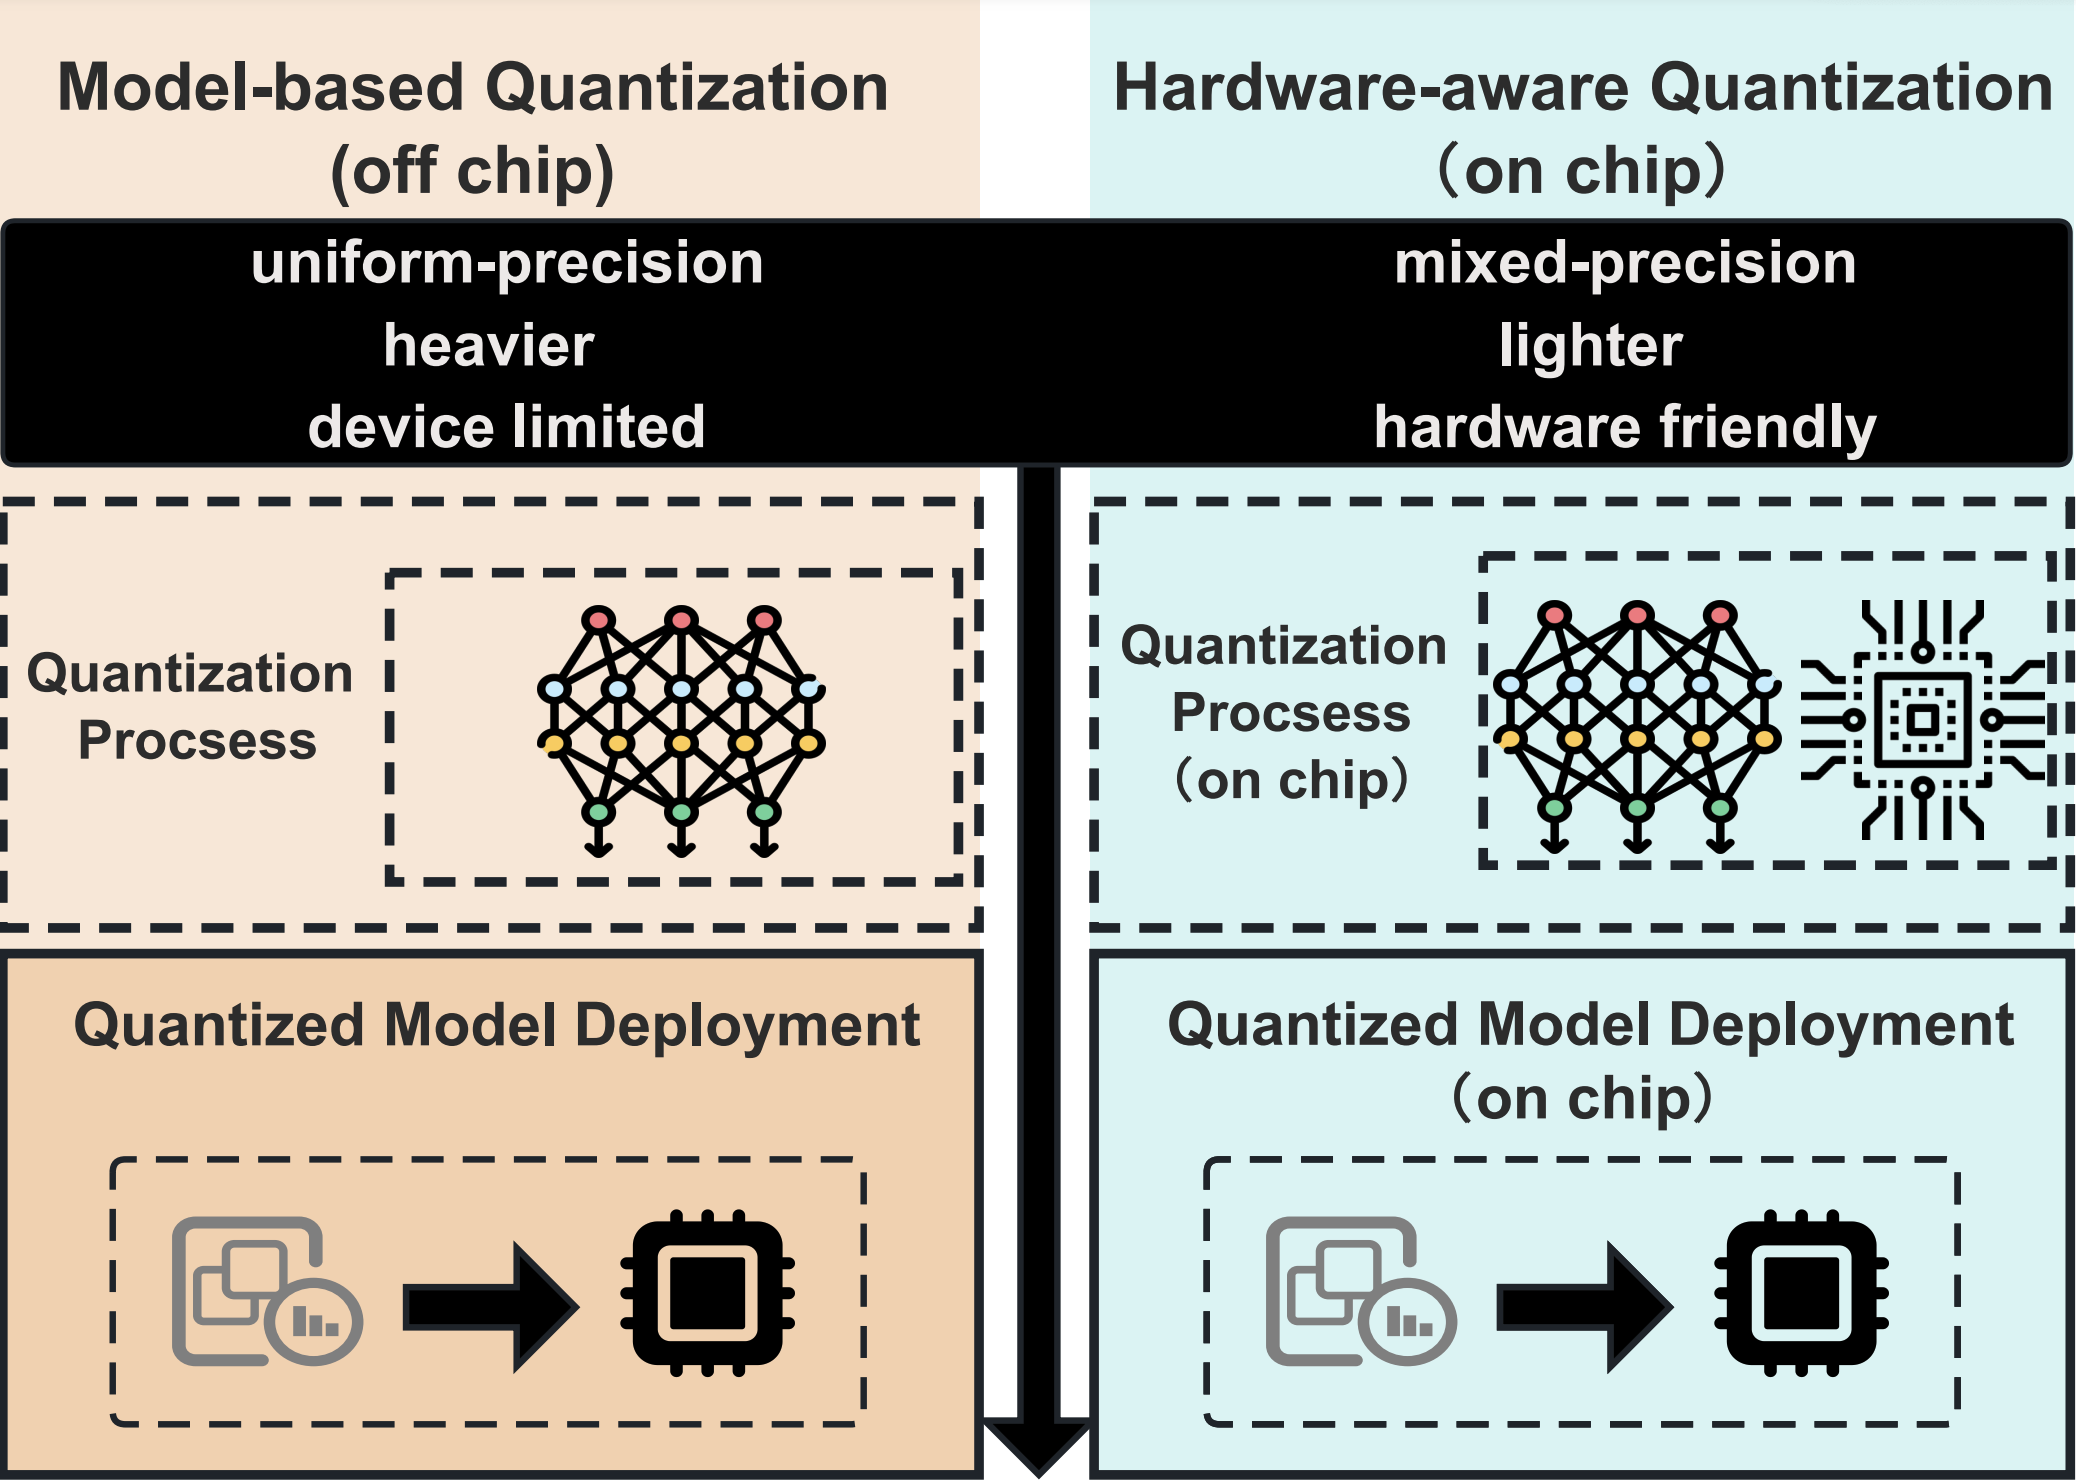
On-Chip Hardware-Aware Quantization for Mixed Precision Neural Networks
Wei Huang, Haotong Qin, Yangdong Liu, Jingzhuo Liang, Yulun Zhang, Ying Li, Xianglong Liu
- Combine IP-core-level chip runtime clock and power awareness with network sensitivity, achieving a better balance of computational efficiency and accuracy on edge devices.
- Allow target networks to be compressed and deployed with high accuracy on edge chips with limited computational resources and ultra-low power consumption.
- Efficiently perform online quantization and optimization without additional devices or data access.
📖 Educations
- 2023.09 - (now), Ph.D. Student in Department of Electrical Electronic Engineering, The University of HongKong.
- 2019.09 - 2023.06, B.Eng. in Computer Science, School of Computer Science and Engineering, Beihang University.
🗒️ Academic Services
- Conference Reviewer: ICLR, Neurips, ICML, ECCV, CVPR, ICCV
- Journal Reviewer: IEEE TPAMI, Neural Networks.
- Program Committee member for Practical Deep Learning Workshop, IEEE CAI 2024.
🎖 Honors and Awards
-2023 Outstanding Graduate, Beihang University.
-2023 Outstanding Project of the 16th National College Student Innovation and Entrepreneurship Competition, China.
-2022 Outstanding Project of the 15th National College Student Innovation and Entrepreneurship Competition, China.
💻 Internships & Teaching Services
- 2026.03 - Now, Research Scientist Intern, NVIDIA.
- 2025.06 - 2026.02, Multimodal Large Language Model Intern, NVIDIA.
- 2022.09 - 2023.01, AI algorithm internship on model inference acceleration, Enflame, China.
- 2022.08 - 2023.01, TA for Frontiers in Artificial Intelligence, Beihang University.
- 2022.08 - 2023.01, TA for Computer Hardware Basics, the head of TA team, Beihang University.
- 2021.08 - 2022.01, TA for Computer Hardware Basics, the head of TA team, Beihang University.
- 2021.03 - 2021.06, TA for Discrete Mathematics, the head of TA team, Beihang University.